Open-weight models,
optimized for your hardware
See how much faster yasp-optimized open-weight models run on specific hardware compared to standard vLLM setups, with transparent, like-for-like benchmarks.
Last updated: November 9, 2026
LLM inference benchmarks by model
New combinations of workloads, models, and hardware are constantly being added.
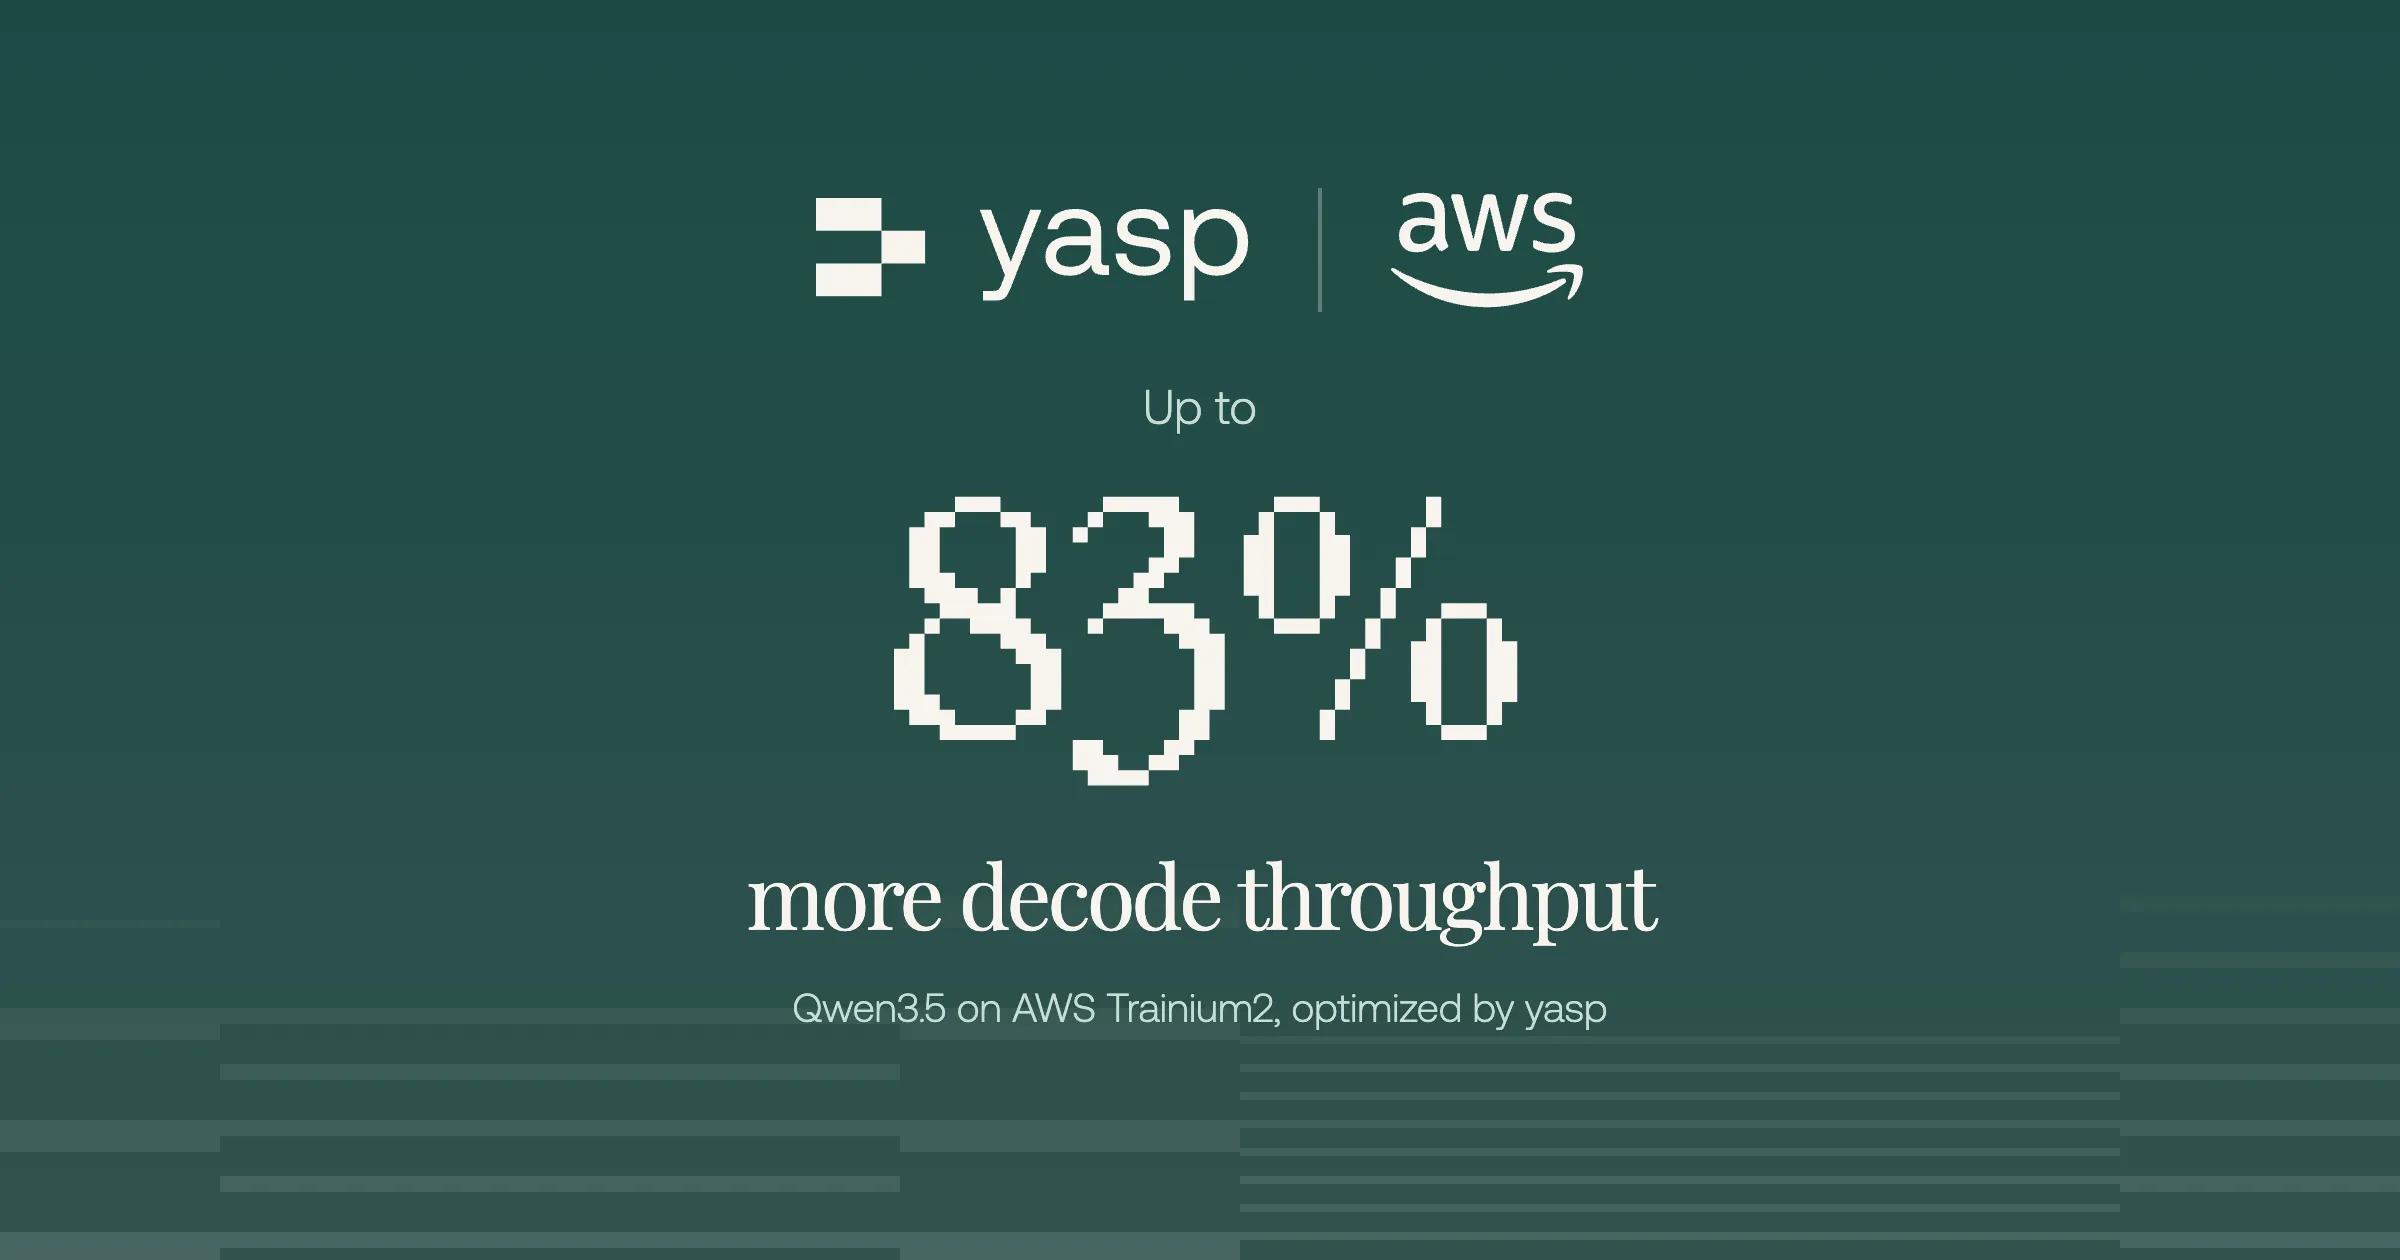
Benchmarked on hardware from AMD, NVIDIA, AWS


Methodology
How we measure
Each model runs on the hardware shown in its row, once with the baseline and once with the yasp-optimized configuration. Speedup is yasp's total tokens per second divided by the baseline's at the same prompt length and load. Baselines name their serving engine, version and precision.
Two prompt lengths
Short prompts of about 20 input tokens and long prompts of about 8,450 input tokens.
Six load levels
From 4 to 128 concurrent users. Each model card shows the level you pick, the header names the peak and where it was measured.
One load generator
Rows against stock vLLM use GuideLLM at 180 s per level, the version is listed with each row. Rows against a published FP8 inference report use that report's load generator.
Checked accuracy
Every optimized build is compared with the original model on KL divergence, top-1 agreement and benchmarks such as GSM8K before it is published.
Reading the board
Five numbers decide
most deployments
Total tok/s
Output tokens per second across all concurrent users. It decides how many users one GPU can serve, and therefore your cost per token.
Per user tok/s
The generation speed a single user sees, calculated as 1000 divided by TPOT.
TTFT p50
Time to first token, median. How long a user waits before the answer starts to appear.
TPOT p50
Time per output token, median. How quickly the answer streams once it has started.
Speedup
yasp's total throughput divided by the baseline's on the same hardware and load. 1.00× is the baseline.
Request a model
Benchmark your model
on your hardware with yasp.
Tell us which model you run and on which hardware. We measure your current setup against the yasp-optimized version on the same hardware, and a yasp engineer walks you through the results.
FAQs
What the numbers mean, and where they come from.
A speedup of 1.5× means the same GPU serves 1.5 times as many tokens at the same load. Put differently, your cost per token drops by about a third, without new hardware and without changing the model. Click Deploy on any row to get that configuration for your setup.
Speedup is yasp’s output token throughput divided by the baseline’s, on the same hardware, with the same prompt and output lengths and the same number of concurrent requests. Both sides are measured with GuideLLM, 180 seconds per load level. Pick a prompt length and a load level at the top of the board, or open all load levels on any row to see every point.
Each row compares against a standard serving setup on the same hardware, for example stock vLLM with the version and precision shown in the row. Both sides run the same model and are measured the same way.
Each optimized version is compared with the original model before it is listed: KL divergence and top-1 token agreement on its outputs, task accuracy (GSM8K or HumanEval) and MT-Bench quality scores. Where a configuration uses lower numeric precision or a relaxed accuracy limit, the row says so, and the checks for each row are listed under all load levels.
Yes. Tell us which model you run and on which hardware in the form above. We measure your current setup against the yasp-optimized version and walk you through the results with an engineer.
Today yasp optimizes models for NVIDIA, AMD and AWS Trainium. If your hardware is missing, request a benchmark.


